
Key Takeaways
- Google can render JavaScript, but crawling, rendering and indexing are separate stages and the rendered result still needs to contain the useful content.
- OpenAI and Perplexity publish crawler and robots.txt information, but their public documentation does not promise that every page receives full browser-style JavaScript rendering.
- Put the primary answer, headings, links and essential metadata in the HTML returned by the server whenever practical.
- A Next.js, React or headless website is not automatically good or bad for search. The production output and crawl path matter.
- Test the real URL with HTML inspection, Google URL Inspection, server logs and disabled-JavaScript checks before blaming an AI platform.
ChatGPT, Google AI Overviews and Perplexity may all discover information from JavaScript websites, but you should not assume they render every application in the same way.
Google describes a rendering system that runs JavaScript. OpenAI and Perplexity document their search crawlers and access controls, but neither public crawler page promises a complete browser session for every URL.
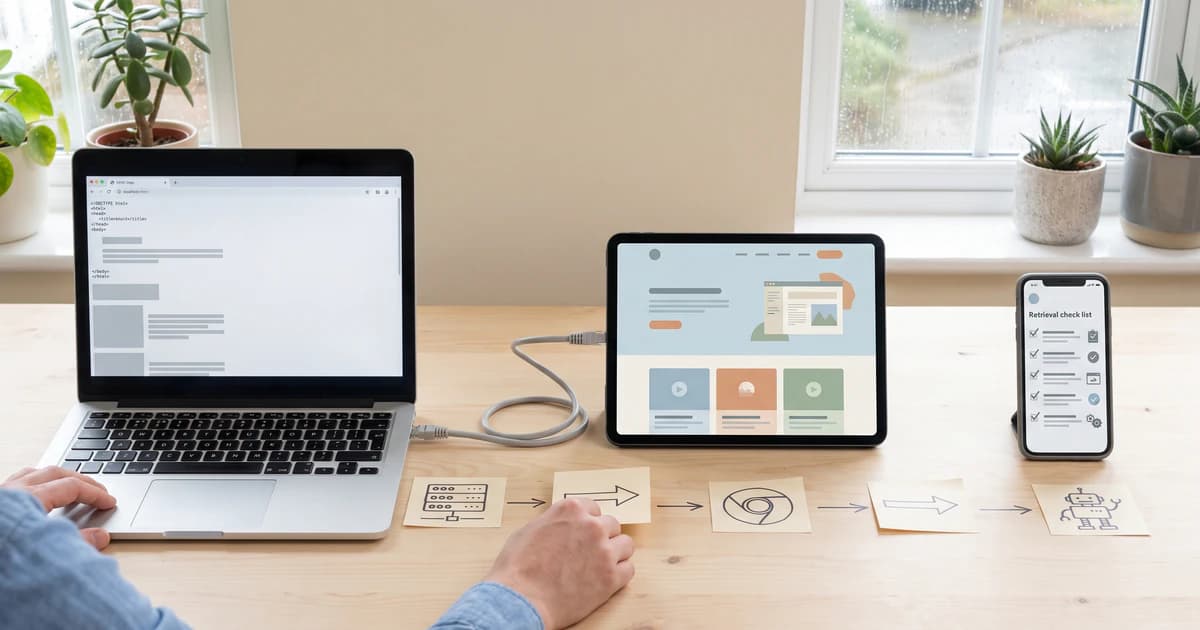
The dependable approach is to make important public content available in the initial or server-rendered HTML, then use JavaScript to enhance the experience.
Separate Crawling, Rendering and Indexing
These terms are often treated as one event.
Crawling means requesting a URL and its resources.
Rendering means processing HTML, CSS and JavaScript to produce the page state a browser would display.
Indexing means analysing eligible content and storing information that may be used for search.
Retrieval and citation happen later, when a search or AI system selects sources for a particular question.
A crawler may fetch the URL but never execute the script that loads the article. A renderer may run but meet an API error. A search engine may index the page and still decide that another source is a better answer.
This is why “the bot visited” is useful evidence, not proof of visibility.
What Google Documents
Google's JavaScript SEO basics describes a crawl, render and index process. Googlebot queues pages for rendering, runs JavaScript and uses the rendered HTML to index the content.
The wider guide to optimising content for AI search explains why reliable delivery and a clear source page need to work together.
The documentation also explains practical risks:
- server and client errors;
- blocked JavaScript or CSS;
- unsupported or failing browser features;
- content that requires user interaction;
- links that are not normal crawlable anchors;
- changing canonical and robots directives with JavaScript;
- soft 404 behaviour in single-page applications.
Google can render JavaScript does not mean every implementation is equally efficient or dependable. Rendering consumes resources and can be delayed. If the core answer is already in the HTML, Google and other tools have less work to do.
For AI Overviews and AI Mode, Google's AI-feature guidance says pages need to be indexed and eligible for a normal Search snippet to appear as supporting links. There is no separate JavaScript route for AI visibility.
What OpenAI Documents
OpenAI's crawler documentation identifies OAI-SearchBot as the user agent used to surface and link websites in ChatGPT search. It gives robots.txt guidance and published IP ranges.
The page does not promise that OAI-SearchBot runs a complete client-side application like a current desktop browser. That absence is important. It would be unsafe to tell a client that content behind a JavaScript request is definitely available merely because robots.txt allows the crawler.
Check actual behaviour:
- Can OAI-SearchBot request the page?
- Does the CDN return 200, 403, 429 or a challenge?
- Is the important answer in the returned HTML?
- Are the internal links present as ordinary anchors?
- Does the page rely on cookies or a session?
- Is the API used by the browser public and crawlable?
OpenAI's publisher FAQ explains search inclusion and referral tracking. It does not turn a crawler visit into a citation guarantee.
What Perplexity Documents
Perplexity's official crawler documentation says PerplexityBot is designed to surface and link websites in search results. It recommends allowing the user agent in robots.txt and permitting its published IP ranges.
Its robots.txt help article explains the company's stated approach to disallowed content.
Those sources are useful for access. They do not state that PerplexityBot executes all client-side JavaScript or waits for every asynchronous request. Treat crawler access and browser rendering as different checks.
Why Client-Only Content Goes Missing
A client-rendered page may initially return:
- a nearly empty application container;
- a loading message;
- JavaScript bundle references;
- generic metadata shared by every route.
The browser downloads scripts, runs them, requests content from an API and constructs the article. Several things can break:
The Script Fails
A bundle error, unsupported feature or missing environment variable can leave the page empty.
The API Is Blocked
The HTML may be public while the content endpoint requires a token, cookie, allowed origin or browser challenge.
The Content Arrives Too Late
An automated renderer may stop before a slow request finishes.
Interaction Is Required
Content behind a click, infinite scroll, accordion or consent flow may not be discovered.
Routes Return the Same HTML
A single-page application can return a successful shell for missing URLs. That makes errors difficult for crawlers to recognise.
Metadata Is Added Only in the Browser
Canonical links, titles, descriptions and structured data may not be present until after script execution, or may conflict with server output.
None of this is unique to AI search. It is a web-delivery issue that AI-search interest has made more visible.
Server Rendering, Static Generation and Hydration
Modern frameworks offer several ways to send useful HTML.
Static Generation
The page is built in advance. It is a strong fit for articles and service pages that change on a controlled schedule. A CDN can return complete HTML quickly.
Server-Side Rendering
The server builds the HTML when requested, or from a recent cache. This suits content that needs fresher data or request-time logic.
Incremental Regeneration
A static page can be refreshed in the background according to the framework's caching design. It combines fast delivery with controlled updates.
Client-Side Rendering
The browser builds most content after loading JavaScript. This can be appropriate for private dashboards and highly interactive tools, but it is a fragile default for public editorial content.
Hydration
The server sends HTML and JavaScript attaches interactive behaviour in the browser. The visible core should not disappear if hydration fails.
A good architecture can mix these methods. Publish the service description and article in HTML. Load a live calculator or account-specific result on the client.
Is Next.js Better Than WordPress for This?
The framework name does not answer the rendering question.
WordPress usually returns article HTML from the server, but a heavy page builder can still hide content behind scripts or produce poor links. Next.js supports server rendering and static generation, but a developer can still build a client-only shell.
Inspect the output, not the sales claim.
For a migration, our WordPress-to-Next.js rebuild guide explains the wider URL, content and SEO controls. The WordPress-to-Next.js migration service includes planning for server output, redirects and launch checks.
A Practical Testing Method
1. Request the Raw HTML
Use a normal HTTP client or browser “view source” on your own public page. Search for the title, main answer, headings, internal links and structured data.
If the raw response contains only a shell, document which content depends on JavaScript.
2. Disable JavaScript in a Test Browser
Reload representative pages. The design does not have to remain fully interactive, but public information and navigation should make sense.
Test:
- home page;
- category page;
- service page;
- article;
- product page;
- contact route;
- 404 page.
3. Use Google URL Inspection
Inspect the live URL and rendered output. Compare the canonical, screenshot and page resources with what a user sees. Remember that this confirms Google testing, not another platform's renderer.
4. Review Logs
Check origin, CDN and firewall records for documented crawler user agents and verified IP ranges where the platform publishes them. Look for status, response size, timing and repeated failures.
Do not blindly allow any request that copies a user-agent string. Use the platform's verification guidance and a considered bot policy.
5. Inspect the Network Dependency
If content comes from an API, ask:
- Is the endpoint available without a browser session?
- Does it return the same public content?
- Does it have a stable URL?
- What happens when it is slow?
- Can it be cached safely?
- Is private data separated?
6. Test After Deployment
A local build can work while production security, caching or environment settings fail. Recheck the public URL after every material rendering change.
Our website audit and consultation can document these layers without assuming a rebuild is required.
Make Important Content Easy to Retrieve
For pages intended for public search:
- return a useful title and main content in HTML;
- use real anchor links with href values;
- give each page a stable canonical URL;
- return honest 404 and redirect responses;
- avoid requiring interaction to reveal the only copy;
- place visible structured data in the server output where practical;
- keep article images and alt text available;
- link from navigable hubs and related pages;
- separate private application content from public marketing content;
- monitor errors and blocked crawlers.
Performance also matters. A server-rendered page that waits ten seconds for several APIs is not robust. Cache appropriate public data and design failure states that retain the core message.
For broader search work, SEO services can connect rendering evidence with indexing, internal links and content quality.
Do Not Build a Separate “AI Version” of Every Page
Some teams consider creating simplified hidden pages for AI crawlers. That creates maintenance and trust problems. Users and crawlers should receive substantially the same public information.
A clean server-rendered source can serve both. Use progressive enhancement for interactive features. If a text alternative is necessary for accessibility or a complex visual, make it genuinely useful and available to users as well.
Google warns against showing materially different content to search engines and people. The safest solution is not special bot copy; it is sound web delivery.
Frequently Asked Questions
Can Google index content that is rendered with JavaScript?
Yes, Google documents a rendering stage in which it runs JavaScript before using the rendered HTML for indexing. Rendering can be delayed or fail, and blocked resources or application errors can remove content, so critical information should still be tested with URL Inspection and rendered output.
Does ChatGPT search execute JavaScript on every page?
OpenAI documents OAI-SearchBot and robots.txt controls, but its public crawler documentation does not promise full browser-style JavaScript rendering for every page. Do not base discoverability on an undocumented assumption. Return meaningful HTML and verify actual requests in server or CDN logs.
Does PerplexityBot render JavaScript?
Perplexity's official crawler page explains PerplexityBot, robots.txt and published IP ranges, but it does not confirm full client-side rendering behaviour. Treat access and rendering as separate questions, and make the primary answer available in the initial HTML.
Is a Next.js website automatically safe for SEO?
No. Next.js can server-render or statically generate pages, but developers can still place important content behind client-only requests, authentication, errors or misconfigured caching. Inspect the production HTML, rendered page, status codes, canonical tags, internal links and structured data rather than relying on the framework name.
How can I test what an AI crawler receives?
Request the URL without running JavaScript, inspect server and CDN logs for the documented user agent and IP information, and compare the initial HTML with the browser result. Use Search Console's URL Inspection for Google. Do not impersonate a bot to bypass access controls; test your own public website and documented permissions.
The Safest Default for Public Content
JavaScript can create excellent interfaces. The risk appears when a public page has no useful content until an undocumented sequence of scripts, APIs and interactions succeeds.
Return the primary answer in HTML. Enhance it with JavaScript. Test the production path and read the logs. That approach helps ordinary search, AI search, accessibility, performance and resilience at the same time.
If you are unsure what the current website sends, contact MattDarm. We can inspect representative templates and recommend the smallest practical fix.